 Gilles Crofils
Generation and judgment are split into separate passes. A Reviewer grades a finished draft from the outside, against an explicit rubric, rather than the writer certifying its own work. One of the scored criteria is a direct penalty for sounding like AI wrote it: repetitive transitions, uniform sentence length, arguments that stay carefully balanced instead of taking a position. The system prompt is blunt about the rest: do not invent backstories, do not hallucinate.
Hallucination gets closed off at the source rather than policed after the fact. Each story carries its own bank of real facts and insights, and the review step checks that the draft actually drew from that bank instead of making something up, and that it hasn't reused what an earlier story already spent.
There's no workflow engine underneath any of this, just a step counter and a background job that re-triggers itself. That's a deliberate match to the actual problem: the real dependency graph here is mostly linear, with 2 genuine join points. Reaching for a heavier orchestration framework would have meant building for a shape of problem that didn't exist.
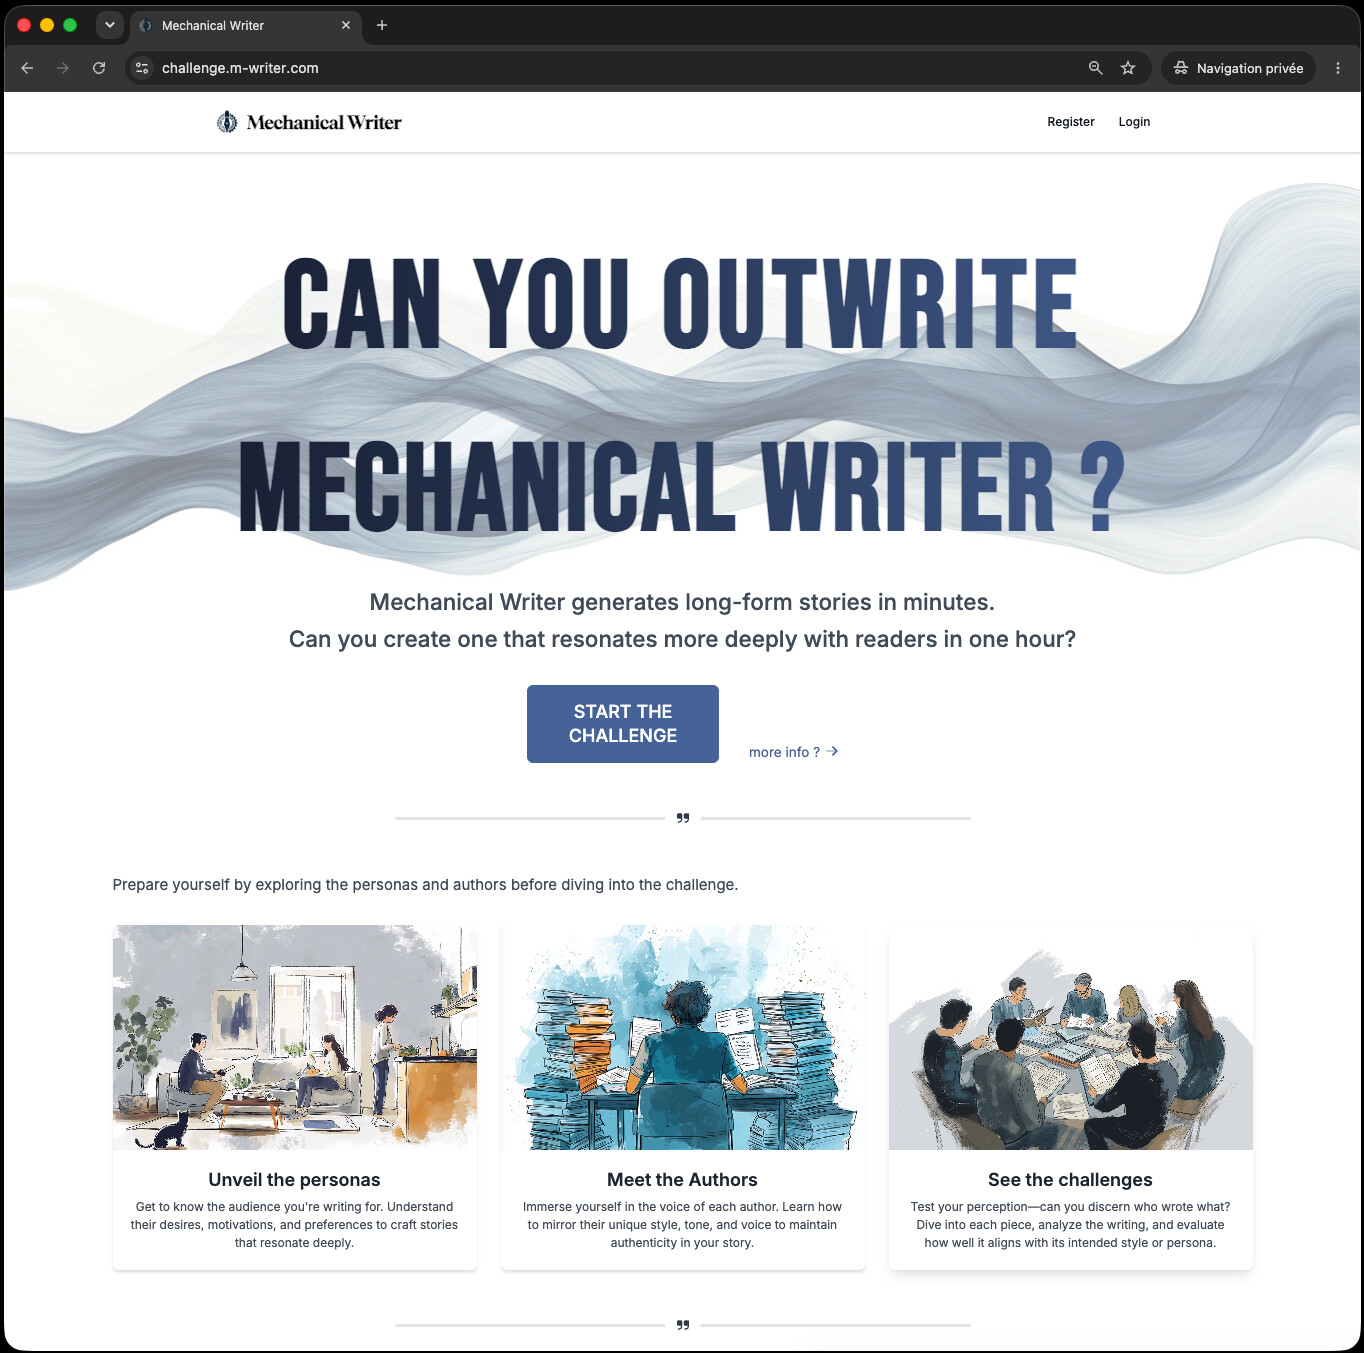
The engine is live at get.m-writer.com. A sibling app, ScribRace, turns the premise into a direct contest: a human picks a topic and an author, writes against the clock, Mechanical Writer generates its own version of the same brief through the same job pipeline, and both get rated blind. Can you outwrite it.
Whether a persona, an author voice, and a fact bank is the right amount of machinery for this, or more than the problem needed, I'm still not sure.